Technical SEO is sometimes presented as a collection of checkboxes: submit a sitemap, install an SEO plugin and improve a speed score. In reality, it is the infrastructure that connects content with search systems. If that infrastructure is unreliable, even strong content may never receive a fair opportunity to compete.
Search visibility begins before ranking
Ranking is not the first step. Google describes Search as a process that includes crawling, indexing and serving results. A URL must first be discovered and fetched. Its content may then need to be rendered and interpreted before it can be stored in the index and considered for relevant searches. Google also makes clear that following best practices does not guarantee crawling, indexing or ranking.
This distinction matters. When a page receives little organic traffic, owners often change keywords or rewrite copy immediately. But if the page is blocked, duplicated, isolated from internal links or repeatedly returns server errors, changing the text does not address the real constraint.
The technical SEO problems website owners frequently miss
1. Accidental indexing restrictions
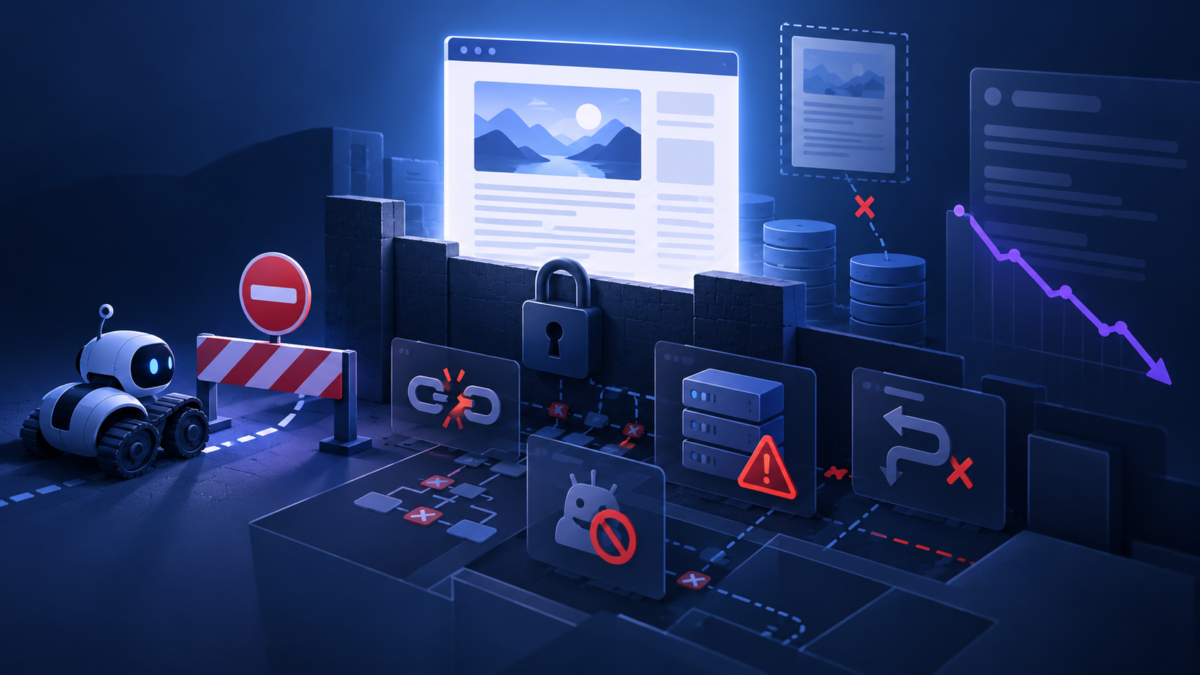
A staging setting, an SEO-plugin option or a copied template can add a noindex directive to important pages. A robots.txt rule can prevent crawling of resources needed to understand the page. Password protection, authentication requirements or firewall rules may also make content unavailable to crawlers.
The details matter. Google explains that a noindex directive must be visible to the crawler. If the URL is blocked in robots.txt, Google may never fetch the page and therefore never see its meta robots instruction. Technical controls should be tested as a system rather than configured in isolation.
2. Duplicate URLs and conflicting canonical signals
The same content may be reachable through HTTP and HTTPS, www and non-www hosts, tracking parameters, print versions, category archives or several product URLs. Duplicate content is not automatically a penalty, but conflicting signals can make search engines spend time on unnecessary URLs and choose a canonical version different from the one the owner intended.
Canonical tags, redirects, internal links and XML sitemaps should agree. A canonical element pointing to one URL while navigation links and the sitemap consistently use another creates ambiguity. The goal is not simply to add canonical tags, but to establish one coherent URL system.
3. Weak internal linking and orphaned content
Search crawlers discover much of the web by following links. Important pages that are absent from navigation, category structures and contextual links are harder to discover and may appear less central to the site. An XML sitemap is useful, but it is not a substitute for a logical information architecture.
Internal links also help users and search systems understand relationships between topics. Descriptive anchor text, sensible breadcrumbs and clear hub pages can communicate which pages are primary and which provide supporting detail.
4. Redirect chains, broken links and incorrect status codes
Website redesigns and migrations often leave chains such as URL A redirecting to B and then to C. Internal links may continue pointing to deleted locations. A missing page may return a visually designed error message with an HTTP 200 status instead of a proper 404. Temporary redirects may remain in place long after a change became permanent.
These faults waste requests, slow navigation and make site structure harder to interpret. At scale, they can also consume crawler attention that would be better directed toward current content.
5. JavaScript that hides essential content
Google can process JavaScript, but its own documentation describes separate crawling, rendering and indexing phases for JavaScript applications. Problems arise when essential text, links, metadata or product information appear only after unreliable client-side requests, user interaction or scripts blocked by consent and security configurations.
Server-rendered HTML is not mandatory for every project, but primary content and navigation should not depend on fragile execution paths. A page should also be tested with rendered HTML, not only by viewing its original source.
6. Poor mobile implementation
A responsive layout can still be difficult to use. Oversized cookie banners, unstable menus, tiny controls, text pushed below decorative images and content that differs between desktop and mobile all damage the real experience. Technical testing should therefore include common phone widths and actual interaction, not merely confirmation that the page does not overflow horizontally.
7. Slow and unstable page experience
Core Web Vitals measure real-world aspects of loading performance, responsiveness and visual stability. Google recommends achieving good results both for users and for Search. Slow server response, oversized images, render-blocking CSS, excessive JavaScript and layout shifts can each degrade those metrics.
However, the correct conclusion is not that a perfect Lighthouse score guarantees high rankings. Google explicitly states that there is no single page-experience signal and that relevance remains fundamental. Performance is best understood as one part of overall quality: it can remove friction and support visibility, but it cannot replace useful content or search intent.
8. Server, DNS and availability problems
Intermittent 5xx responses, slow uncached pages, DNS failures, TLS problems and aggressive security rules can affect both visitors and crawlers. A site may look fast to its owner because frequently visited pages are cached, while first-time requests or requests from another region take many seconds or fail entirely.
This is why a single speed test is not enough. Logs, uptime monitoring, uncached tests and Search Console reports provide different parts of the picture.
How technical faults translate into weaker rankings
Not every fault is a direct ranking factor. The practical chain is usually more complex:
- If a crawler cannot access a page, the page may not be indexed.
- If signals are contradictory, a different canonical URL may be selected.
- If internal linking is weak, important content may be discovered slowly and appear peripheral.
- If rendering fails, search systems may receive incomplete content or links.
- If a page is slow or unstable, users are more likely to abandon it and complete fewer meaningful actions.
- If maintenance problems create outages or security incidents, the entire site can lose reliability.
Technical SEO therefore affects visibility through several mechanisms. Some are direct prerequisites for indexing. Others shape page experience, site quality and the ability of content to perform once it is discovered.
A practical diagnostic order
When organic visibility declines, the most efficient approach is to investigate in layers:
- Availability: Does the server respond consistently with the correct status code?
- Crawlability: Can search crawlers access the URL and its important resources?
- Indexability: Are robots directives, canonicals and redirects correct?
- Discovery: Is the page linked from relevant parts of the site and included in the sitemap?
- Rendering: Is the main content present after scripts and consent rules are applied?
- Mobile experience: Can a visitor read, navigate and interact without obstruction?
- Performance: What do field data, lab tests and server measurements show?
- Content and intent: Does the page genuinely answer the searcher’s need better than alternatives?
Technical SEO is maintenance, not a one-time setup
Websites change continuously. Plugins are updated, redirects accumulate, templates are modified, new tracking tools are added and old content is reorganized. A site that was technically clean two years ago may now contain hundreds of small inconsistencies.
The best technical SEO work does not chase isolated scores. It creates a reliable foundation: pages that load consistently, expose their content clearly, use coherent URLs, work well on mobile and help both visitors and search systems understand what matters.
Primary sources
- Google Search Central: How Google Search works
- Google Search Central: Crawling and indexing
- Google Search Central: JavaScript SEO basics
- Google Search Central: Using noindex
- Google Search Central: Core Web Vitals and Search
- Google Search Central: Page experience in Search
Which technical SEO issue has caused you the most trouble?
Results
0 confirmed votes